Home/Blog/Liquid Cooling vs. Air Cooling for High-Density AI Racks
Liquid Cooling vs. Air Cooling for High-Density AI Racks
A cooling architecture decision made early in a federal AI infrastructure program can quietly determine that program’s performance ceiling years later. Air cooling served enterprise data centers well for decades, but the power density of modern AI accelerators has moved past what air can practically dissipate, and the threshold where liquid cooling stops being optional is more concrete than most procurement conversations treat it.
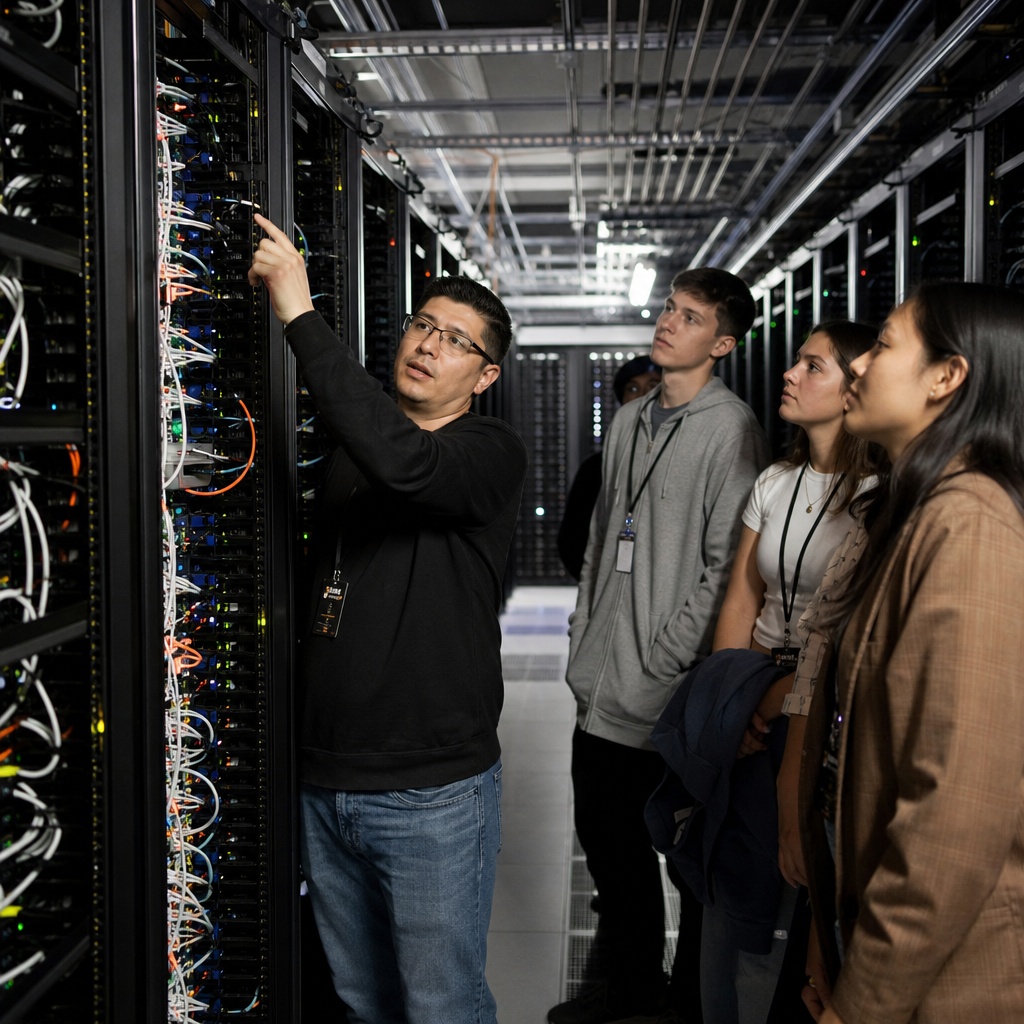
Air cooling systems built for traditional enterprise IT were designed around cabinet densities in the high single digits to low double digits of kilowatts. Modern AI accelerators have moved well past that envelope. A single NVIDIA H100 GPU draws roughly 700 watts, the B200 draws up to 1,200 watts under liquid cooling, and a full GB200 NVL72 rack, the reference architecture for large-scale AI training, pulls approximately 120 kilowatts total. Traditional air-cooled racks top out around 35 to 41 kilowatts, an order of magnitude below what current-generation AI infrastructure requires.
The physics behind this gap is straightforward: water conducts heat roughly a thousand times more effectively than air. Below a certain density, moving more air through a rack is a workable solution. Above it, the airflow required becomes impractical, and air cooling systems already account for up to 40 percent of a typical data center’s total electricity consumption trying to compensate.
Where the Threshold Actually Sits
The decision isn’t binary at every density level, it depends on rack power, energy cost, and growth trajectory, but the general thresholds are becoming well established across the industry.
Rack Density
Typical Approach
Consideration
Below 20 kW
Air cooling remains viable
Standard enterprise cooling infrastructure is generally sufficient
20-30 kW
Evaluation point
Many organizations begin seriously evaluating liquid cooling as density approaches this range
30 kW+
Liquid cooling TCO advantage
At roughly $0.12/kWh, direct-to-chip liquid cooling’s ten-year total cost of ownership crosses below air cooling at approximately this density
50 kW+
Liquid cooling generally required
Air-based heat removal reaches practical limits; direct-to-chip or immersion cooling becomes the standard approach
100 kW+
Purpose-built liquid or immersion cooling
Densities at this level, increasingly common in current GPU reference architectures, require cooling designed specifically for the deployment
The Performance Cost of Undersized Cooling
Insufficient cooling doesn’t just create a facilities problem, it directly degrades the performance the hardware investment was meant to deliver. A documented example from a research computing environment illustrates this clearly: a cluster running a large fine-tuning job saw GPU junction temperatures hit 83 degrees Celsius roughly six hours into each run, triggering automatic clock speed reduction that stretched a 22-hour job to 31 hours. Switching to a properly sized liquid cooling loop for the same GPUs and the same workload brought junction temperatures down to 44 degrees Celsius and cut training time back to 22 hours, a 29 percent improvement from the cooling change alone, with no change to the underlying compute hardware.
This is the practical case for treating cooling architecture as a performance specification, not just a facilities line item. A GPU cluster throttling under thermal load delivers less than its rated performance exactly when a workload demands the most from it.
Liquid Cooling Approaches
Direct-to-chip: cold plates attached directly to CPUs, GPUs, or accelerators, removing the largest heat source from room air while keeping servers otherwise serviceable through familiar operating models
Rear-door heat exchangers: liquid-cooled doors mounted on the rack that remove heat from exhaust air before it enters the room, a lower-complexity option than full direct-to-chip deployment
Immersion cooling: hardware submerged in a dielectric fluid bath, delivering the highest heat rejection density but requiring more significant changes to maintenance, warranty, and facility assumptions
Most current deployments favor direct-to-chip cooling as the practical middle ground, meaningful density gains without the full operational shift immersion cooling requires.
What This Means for Federal Procurement Planning
Cooling architecture needs to be part of the workload assessment conducted before hardware is finalized, not a facilities question addressed after equipment arrives. A program specifying GPU infrastructure at current-generation density levels without confirming the facility’s cooling capacity, or budgeting for a cooling infrastructure upgrade, risks discovering a genuine mismatch only once hardware is on site, a costly and disruptive point to find it.
Confirm current facility cooling capacity against the rack density your workload assessment indicates you’ll need, both at initial deployment and at your program’s growth horizon
Factor cooling infrastructure cost into total cost of ownership calculations, not as a separate line item disconnected from the hardware decision
For programs anticipating growth toward higher-density future GPU generations, evaluate whether liquid cooling infrastructure installed now avoids a more disruptive retrofit later
How Ace Computers Supports Cooling-Informed Procurement
Ace Computers’ workload assessment process includes evaluating the power and cooling implications of a proposed configuration alongside its compute specifications, so cooling architecture decisions are made with the same rigor as GPU and storage selection, rather than as an afterthought discovered during facility planning.
At what rack density does liquid cooling become necessary?
Many organizations begin evaluating liquid cooling as density approaches 20 to 30 kW per rack. At roughly 30 kW and typical commercial electricity rates, direct-to-chip liquid cooling’s total cost of ownership crosses below air cooling. Above 50 kW, air-based cooling generally reaches its practical limits.
Can undersized cooling affect AI training performance, not just facility operations?
Yes. GPUs experiencing thermal throttling reduce clock speed automatically to protect themselves, directly extending training and processing time. Properly sized cooling has been documented to reduce training time by roughly 29 percent for the same hardware and workload, purely from resolving a thermal bottleneck.
What's the difference between direct-to-chip and immersion cooling?
Direct-to-chip cooling attaches cold plates to specific components like CPUs and GPUs, removing the largest heat source while keeping servers otherwise serviceable in a familiar way. Immersion cooling submerges hardware entirely in a dielectric fluid, offering the highest heat rejection density but requiring more significant changes to maintenance and facility operations.
Can Ace Computers help assess cooling requirements for a federal AI deployment?
Yes. Ace Computers’ workload assessment process evaluates power and cooling requirements alongside compute and storage specifications, helping federal programs confirm facility readiness before a configuration is finalized.